AI data labeling with a human in the loop
AI data labeling in ImageLabeling splits the work the way it should be split: the AI model drafts, people decide. A model is fast at drawing a box around an obvious pallet and poor at knowing that your team counts a half hidden pallet as a separate class. Humans are the opposite. This page explains why we keep a person in the loop on every label, where that person adds the most value, and how review and QA make the combination reliable enough for training data.
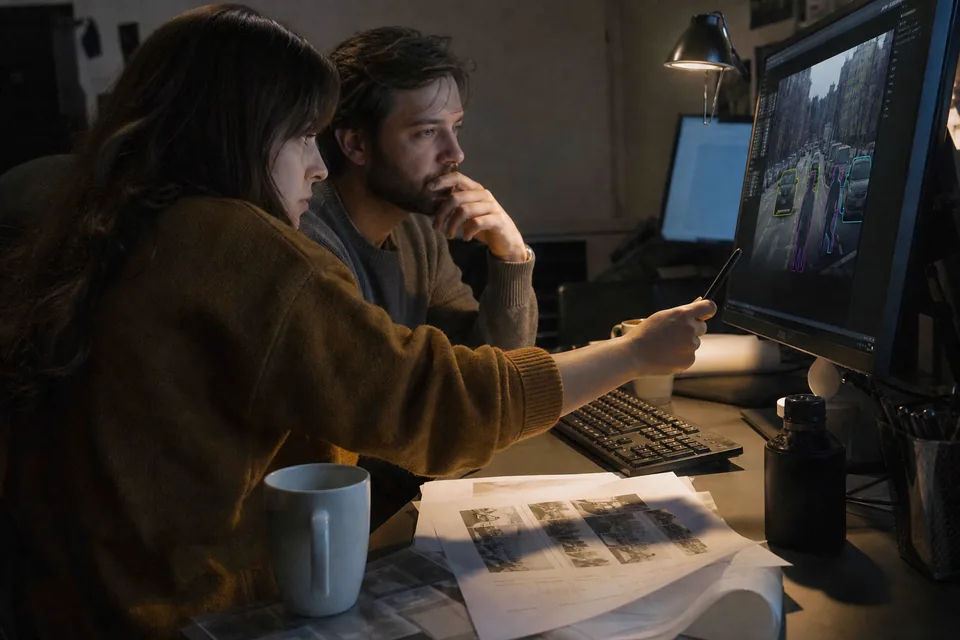
Why AI alone is not enough for training data
A model trained on labels that another model produced inherits that model's blind spots. If the drafting model misses small objects, your detector learns to miss them too. If it confuses two similar classes, the confusion is baked into your dataset. A human check on each label breaks that chain. The person sees the image the way your product will, applies your labeling guidelines, and fixes what the model got wrong before training ever starts.
- Models repeat their own errors, people catch them
- Your class definitions live in your guidelines, not in a generic model
- Edge cases need judgment, not a confidence score
What the model does and what people do
The model drafts boxes, polygons, masks, keypoints and image classes for the classes in your schema, each with a confidence value. People accept, edit or reject each draft, draw what the model missed, set attributes such as occluded or truncated, and answer the hard questions: is this a defect or a reflection, is this person wearing a helmet or holding one. Reviewers then approve the result or send it back. The technical side of drafting is on the auto labeling page.
An AI annotation tool with review built in
Review is not an add-on. Every project can require a reviewer after the labeler, and a send back carries a comment that points to the exact object. On Team and higher, consensus runs on a sample of images: two people label the same image and disagreements go to the issue queue. On Business and higher, each labeler gets a QA score, so you know whose work can be trusted to review others.
- Labeler then reviewer on every image
- Send back with a comment on a specific object
- Consensus on a sample (Team and higher)
- QA score per labeler (Business and higher)
Turning your guidelines into the schema
Most labeling disagreements come from vague rules. Put the rules where labelers work. Classes, colors, attributes and hierarchical classes live in the label schema, and the same schema guides AI drafts. When a reviewer sends back a label with a comment, that comment becomes part of the project history, so the next labeler sees how an edge case was decided.
When you need more people in the loop
Some teams have the data but not the labelers. On Business and Enterprise, data annotation services add vetted annotators from 899 USD per month per dedicated annotator. They work in your workspace under your schema, your reviewers and your QA scores, so outside help never means outside quality rules.
Your images stay yours
Images are encrypted in transit and at rest and used only to label your dataset. They are never used to train third party models, and you can request deletion. More on the security page.
What AI data labeling costs
Every plan includes a monthly AI quota: 1,000 pre-labeled images on Starter at 49 USD per month, 3,500 on Team at 149 USD, 12,000 on Business at 499 USD and 35,000 on Enterprise at 1,499 USD. Yearly billing halves each price. Human labeling is not metered. See pricing, and the overview of controls for managers on the data annotation platform page.
FAQ
How accurate are the AI drafts?
They are a first draft with a confidence value per object. Your labelers accept or fix every object, and with review on, nothing reaches export unreviewed.
Can a reviewer see which labels came from AI?
Yes. The label history shows whether an object started as an AI draft and who accepted or changed it.
Is AI data labeling safe for medical images?
The tool labels images for research and model training. It is not a diagnostic device and makes no clinical claims.
Do I need my own model for the drafts?
No. Drafting runs inside the workspace on your schema. You only define classes and, if you want, a short prompt per class.
Let AI draft and your team decide
Create your workspace, set your classes and review your first AI drafted batch.